
Your RAG bill is mostly reading.
Clarke reads for less.
Clarke is a Sonnet-class model, tuned and served on Radium at $1.50 per million input tokens, with no tokens-per-minute limit. Change the base URL, key and model name, and your retriever, index and SDK stay as they are.
Start with $25 in free credit. No card required.



One model for each stage of your RAG pipeline
Clarke matches retrieval and chat without frontier pricing. Route harder synthesis to Hal, and extraction to Tycho.
Hal 1.0
Comparable to Anthropic
Opus 5.5 or OpenAI GPT-6 Astra
Clarke 1.0
Comparable to Anthropic
Sonnet 5.5 or OpenAI GPT-6 Sol
Tycho 1.0
Comparable to Anthropic Haiku
5.5 or OpenAI GPT-6 Luna
Designed for the work you already run these models for.
Ingest & chunk
Structure and label documents before indexing
Embed & index
Split, vectorise and store.
Retrieve
Match the query to the nearest chunks
Generate
Read the chunks, write the answer
Scored against frontier models on real product tasks
Independent Radium benchmark, not endorsed by Anthropic. Claude and Opus are Anthropic PBC trademarks, used for identification only. Results are a single run, provided “as is,” and not a guarantee of future performance. See the full benchmark report
Control the cost per answered question
Every new account gets $25 in credit. No card required.
Built for the part of RAG you pay for
Retrieved passages are most of the input, and input is most of the bill.
$1.50 / 1M
Clarke's price per million input tokens, 25% below Sonnet 5.5 at list. A question with eight retrieved passages costs under a cent.
No limit
1,000 requests a minute with a burst of 33, set per organization from day one. A 9am spike in questions is just traffic.
Up to 90%
Saved with prompt caching on the system prompt and instructions that repeat on every query. Only the retrieved chunks change.
What changes
The base URL in your client
The model string
The invoice
What stays the same
The retriever and reranker
The Anthropic or OpenAI SDK
Tool and function calls
Parallel tool calls
Streaming, including tool deltas
Structured output
Retry and error handling
Evals, tracing and observability
What the difference looks like monthly
Same tasks, different rate, two bills to compare.
Clarke 1.0 against Sonnet 5.5 list pricing as of October 2026, for a RAG question with 4,900 input and 350 output tokens.
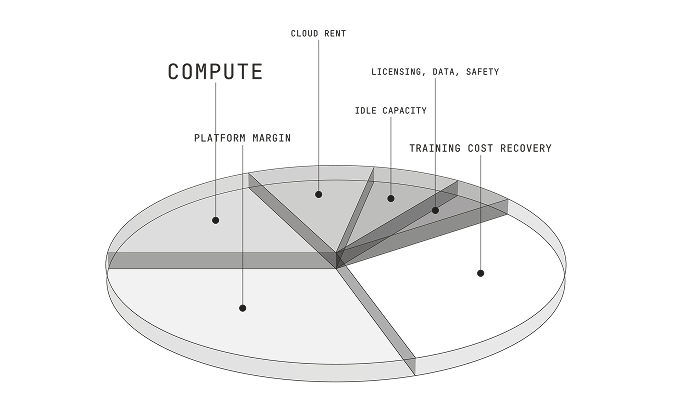
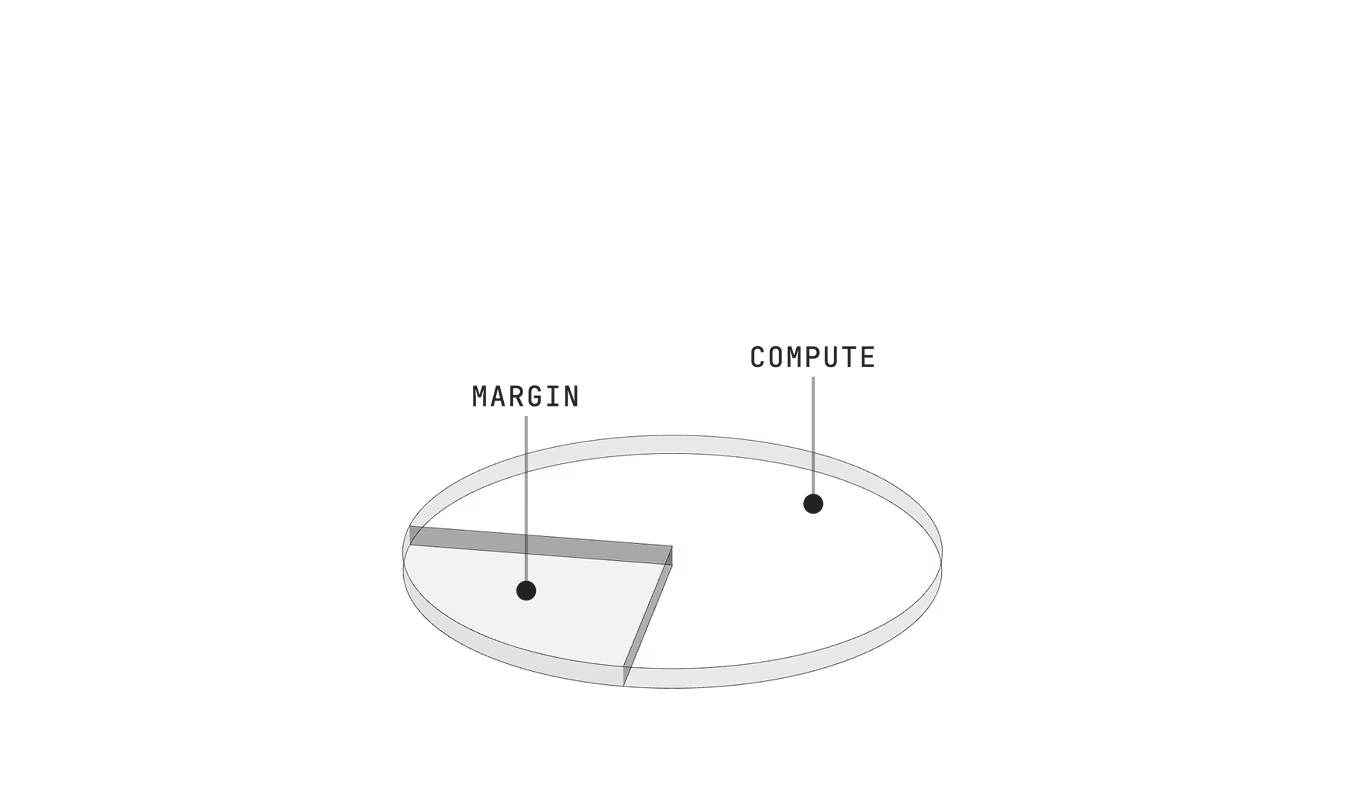
See the workingSix cost layers sit inside a frontier token. Two sit inside ours
The same arithmetic holds whether the call comes from an agent loop or a retrieval chain.
The switch is three values, and so is the way back
No. Retrieval, your index and your reranker stay exactly where they are. Radium sits downstream of retrieval and answers the query once the context is assembled.
Not on day one. Embeddings keep running through whatever provider generates them today. Only the generation call, the model that reads the retrieved chunks and writes the answer, points at Radium.
That's the right question, which is why we publish model comparisons instead of asking you to trust a claim. Clarke is scored against the frontier tier it replaces on the same production tasks. Run your own retrieval eval against both endpoints before you decide.
Yes. Tool calling, structured outputs and JSON schema behave the same way, because the API is compatible rather than similar. If your chain asks the model to return sources alongside an answer, that shape doesn't change.
Context window and maximum output are published in the model reference. A call that stuffs ten or twenty retrieved chunks into the prompt is a normal request, not an edge case.
It should help more here than almost anywhere else. A RAG system prompt and its instructions repeat on every call; only the retrieved chunks change. Prompt caching is supported and priced separately from the rest of the input.
Clarke for most retrieval and chat traffic. Route to Hal when a query needs multi-hop reasoning across several retrieved documents, and to Tycho for the classification and extraction steps upstream in ingestion.
1,000 requests per minute with a burst of 33, and no tokens-per-minute limit, set per organization from day one. There's no spend history to build first. Above 1,000 requests a minute you can still get a 429, so keep a retry with backoff for those.
Point a staging chain at the endpoint and run the queries you already run. Compare cost per answered query on both endpoints before anything user-facing changes.
Change the three values back. Nothing upstream of the generation call, your retriever, your index, or your chunking, ever pointed anywhere else.