Agent workflows

Production models for 
agent workloads

Built for the reasoning a loop demands, and priced for running it all day. Same SDK, one line of configuration.

Start with $25 in free credit. No card required.

Get your API key
Drop‑in for
Anthropic SDK
OpenAI SDK
Git Hub Copliot
Claude Code CLI
LangGraph
Vercel AI SDK
LlamaIndex
VS Code
Lite LLM
Anthropic SDK
OpenAI SDK
Git Hub Copliot
Claude Code CLI
LangGraph
Vercel AI SDK
LlamaIndex
VS Code
Lite LLM
Our Models

Our top‑tier models optimized for 
production workloads

Hal reasons like a frontier model, so the loop does not get longer.

Coding
Agents
Tool Calling

Hal 1.0

Maximum Capability

Comparable to Anthropic
Opus 5.5 or OpenAI GPT-6 Astra

Retrieval
RAG
Chat

Clarke 1.0

Balanced Performance

Comparable to Anthropic
Sonnet 5.5 or OpenAI GPT-6 Sol

Classification
Extraction

Tycho 1.0

High-Efficiency Scale

Comparable to Anthropic Haiku
5.5 or OpenAI GPT-6 Luna

Rate card

Every tier, priced next to the models it stands in for.

Radium

Anthropic

OpenAI

High-efficiency scale

Tycho 1.0

$0.50 / $2.25

4.7x Haiku 5.5

Claude Haiku 5.5

$0.10 / $0.50

GPT-6 Luna

$0.10 / $0.50

Balanced performance

Clarke 1.0

$1.50 / $7.00

28% less

Claude Sonnet 5.5

$2.00 / $10.00

GPT-6 Sol

$2.00 / $10.00

Maximum capability

Hal 1.0

$2.25 / $13.75

35% to 74% less

Claude Opus 5.5

$4.00 / $20.00

GPT-6 Astra

$10.00 / $50.00

Input / output, USD per million tokens. Anthropic list prices as published on 12 October 2026; Haiku 5.5 shown for prompts up to 100K tokens. OpenAI GPT-6 standard rates as announced in September 2026, for prompts under 272K tokens. Savings use a 70% input / 30% output blend.

Model Comparison

Scored against frontier models on real product tasks

Radium Hal 1.0
50
77
 / 
80
 correct
Anthropic Opus 5.5
50
75
 / 
80
 correct
Tasks in category
Runs per task
Scored by
80
1
Exact-match JSON schema
Radium Hal 1.0
50
20
 / 
20
 correct
Anthropic Opus 5.5
50
15
 / 
20
 correct
Tasks in category
Runs per task
Scored by
20
1
Exact-match JSON schema
Radium Hal 1.0
50
17
 / 
20
 correct
Anthropic Opus 5.5
50
20
 / 
20
 correct
Tasks in category
Runs per task
Scored by
20
1
Exact-match JSON schema
Radium Hal 1.0
50
20
 / 
20
 correct
Anthropic Opus 5.5
50
15
 / 
20
 correct
Tasks in category
Runs per task
Scored by
20
1
Exact-match JSON schema
Radium Hal 1.0
50
20
 / 
20
 correct
Anthropic Opus 5.5
50
20
 / 
20
 correct
Tasks in category
Runs per task
Scored by
20
1
Exact-match JSON schema

Independent Radium benchmark, not endorsed by Anthropic. Claude and Opus are Anthropic PBC trademarks, used for identification only. Results are a single run, provided “as is,” and not a guarantee of future performance. See the full benchmark report

The number that matters

Control the cost per completed task

Every new account gets $25 in credit. No card required.
Get your API key
Dense cluster of white dots scattered against a dark background, resembling stars or particles.
What changes

Two lines of configuration

Point your client at Radium and name a model. The SDK, the loop, the tools, and the evals carry on as they are.

from openai import OpenAI

client = OpenAI(
    api_key="YOUR_API_KEY",
    base_url="https://api.radium.cloud/v1",
)

response = client.chat.completions.create(
    model="hal-1.0",
    messages=[
        {"role": "user", "content": "Hello, Radium!"}
    ],
)

print(response.choices[0].message.content)
import OpenAI from "openai";

const client = new OpenAI({
  apiKey: "YOUR_API_KEY",
  baseURL: "https://api.radium.cloud/v1",
});

const response: OpenAI.Chat.ChatCompletion =
  await client.chat.completions.create({
    model: "hal-1.0",
    messages: [{ role: "user", content: "Hello, Radium!" }],
  });

console.log(response.choices[0].message.content);
curl https://api.radium.cloud/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -d '{
    "model": "hal-1.0",
    "messages": [{"role": "user", "content": "Hello, Radium!"}]
  }'
package main

import (
	"context"
	"fmt"

	openai "github.com/sashabaranov/go-openai"
)

func main() {
	cfg := openai.DefaultConfig("YOUR_API_KEY")
	cfg.BaseURL = "https://api.radium.cloud/v1"
	client := openai.NewClientWithConfig(cfg)

	resp, err := client.CreateChatCompletion(
		context.Background(),
		openai.ChatCompletionRequest{
			Model: "hal-1.0",
			Messages: []openai.ChatCompletionMessage{
				{Role: openai.ChatMessageRoleUser, Content: "Hello, Radium!"},
			},
		},
	)
	if err != nil {
		panic(err)
	}

	fmt.Println(resp.Choices[0].Message.Content)
}
import com.openai.client.OpenAIClient;
import com.openai.client.okhttp.OpenAIOkHttpClient;
import com.openai.models.chat.completions.*;

OpenAIClient client = OpenAIOkHttpClient.builder()
    .apiKey("YOUR_API_KEY")
    .baseUrl("https://api.radium.cloud/v1")
    .build();

ChatCompletion completion = client.chat().completions().create(
    ChatCompletionCreateParams.builder()
        .model("hal-1.0")
        .addUserMessage("Hello, Radium!")
        .build());

System.out.println(
    completion.choices().get(0).message().content().orElseThrow());
using OpenAI;
using OpenAI.Chat;

var client = new OpenAIClient(
    new ApiKeyCredential("YOUR_API_KEY"),
    new OpenAIClientOptions
    {
        Endpoint = new Uri("https://api.radium.cloud/v1"),
    });

var chatClient = client.GetChatClient("hal-1.0");
var response = await chatClient.CompleteChatAsync(
    new UserChatMessage("Hello, Radium!"));

Console.WriteLine(response.Value.Content[0].Text);
import anthropic

client = anthropic.Anthropic(
    api_key="YOUR_API_KEY",
    base_url="https://api.radium.cloud",
)

message = client.messages.create(
    model="hal-1.0",
    max_tokens=1024,
    messages=[
        {"role": "user", "content": "Hello, Radium!"}
    ],
)

print(message.content[0].text)
import Anthropic from "@anthropic-ai/sdk";

const client = new Anthropic({
  apiKey: "YOUR_API_KEY",
  baseURL: "https://api.radium.cloud",
});

const message: Anthropic.Message = await client.messages.create({
  model: "hal-1.0",
  max_tokens: 1024,
  messages: [{ role: "user", content: "Hello, Radium!" }],
});

console.log(message.content[0].text);
curl https://api.radium.cloud/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -d '{
    "model": "hal-1.0",
    "messages": [{"role": "user", "content": "Hello, Radium!"}]
  }'

What changes

The base URL in your client

The model string

The invoice

What stays the same

The agent loop

The Anthropic or OpenAI SDK

Tool and function calls

Parallel tool calls

Streaming, including tool deltas

Structured output

Retry and error handling

Evals, tracing and observability

Cost

What the difference looks like monthly

Same tasks, different rate, two bills to compare.

Monthly spend on frontier agent traffic
Share moved
Estimated monthly savings
$0
0% lower
than current bill

Hal 1.0 against Claude Opus 5.5 list pricing, using real per-task token averages from the production benchmark. See the working

Pricing Breakdown

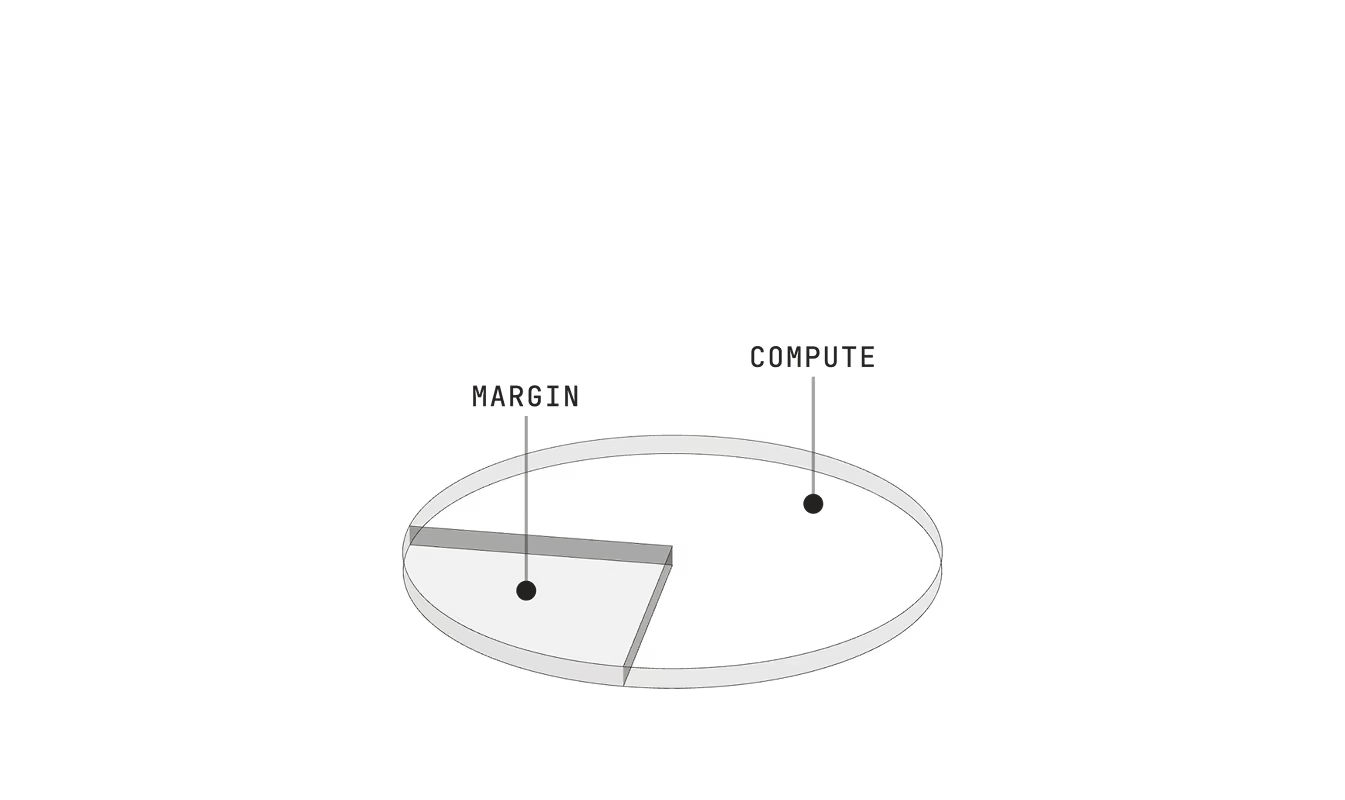
Six cost layers sit inside a frontier token. Two sit inside ours

The same arithmetic holds whether the call comes from an agent loop or a retrieval chain.
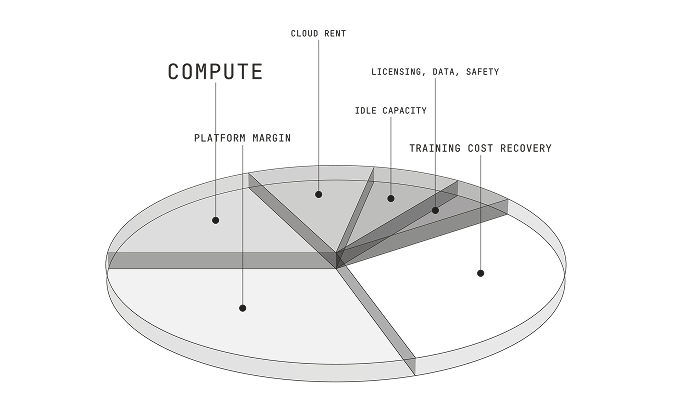
Frontier Token
Radium Token

The switch is one line, and so is the way back
Get your API key
Cost
Will a cheaper model just take more steps and cost us more?

That is the right question, and it is why we publish step counts next to prices. In the measured run Hal took thirty-three steps against thirty-one and finished the same task, so loop length held and the rate difference carried through. Run the same comparison on a task of your own before you believe ours.

What happens when the model gets a step wrong?

The same thing that happens today. Your loop catches it, retries and carries on, and the error codes your retry logic keys on are unchanged.

How does it handle long agent transcripts?

Context window and maximum output are published in the model reference. Transcripts that need compaction get compacted the way they do now, because the request shape has not changed.

Does latency change across a long loop?

Time to first token is comparable, and sustained throughput is what matters once a loop is running. Both are in the benchmark results, measured across a full task rather than a single call.

Does our agent framework work with this?

If it takes a base URL, yes. LangGraph, LlamaIndex, CrewAI, Pydantic AI, the OpenAI Agents SDK, Vercel AI SDK and LiteLLM all work by changing provider config, and there is a written guide for each.

Do our tool schemas need changing?

No. Tool calling, parallel tool calls and streaming tool deltas behave the same way, because the API is compatible rather than similar.

Do we need to change our system prompts?

No, and agent system prompts are usually the most tuned thing a team owns. Re-run your evals as a matter of course rather than because we expect a difference.

What are the concurrency limits when an agent fans out?

Published, and above what most agent traffic needs. Agents burst rather than trickle, so if your ceiling is the problem we raise it rather than throttle you, because we own the capacity.

How do we test this without touching production agents?

Point a staging agent at the endpoint and run the tasks you already run. The harness does it for you and prints cost per completed task on both endpoints.

Can we switch back?

Remove one environment variable. Nothing in the loop changed on the way in.